syed mutaib ali

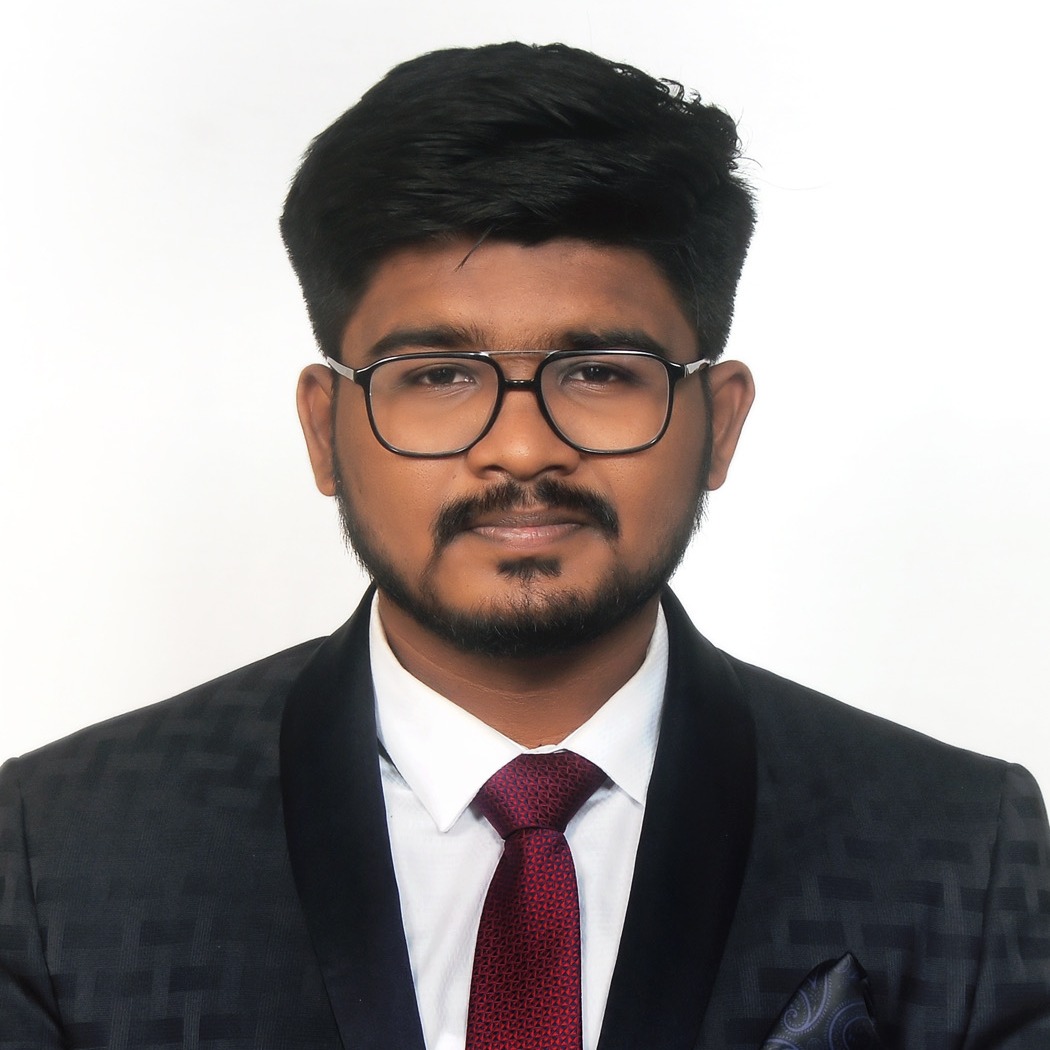
Portrait

Data Engineer / Data Science Engineer with 3+ years of experience building cloud-native data platforms and AI/ML solutions for banking and fintech. Skilled in Python, SQL, Spark, Kafka, Snowflake, AWS, Azure, and PyTorch. Experienced in real-time analytics, fraud detection, credit risk modeling, and portfolio analytics, delivering solutions that reduced analytics latency by 85%, improved payment processing throughput by 5x, and supported regulatory compliance.

Résumé, links and contact below

About

Portrait

Data Engineer / Data Science Engineer with 3+ years of experience building cloud-native data platforms and AI/ML solutions for banking and fintech. Skilled in Python, SQL, Spark, Kafka, Snowflake, AWS, Azure, and PyTorch. Experienced in real-time analytics, fraud detection, credit risk modeling, and portfolio analytics, delivering solutions that reduced analytics latency by 85%, improved payment processing throughput by 5x, and supported regulatory compliance.

Data Scientist with 3+ years of experience designing and deploying AI/ML-driven credit risk, fraud detection, and portfolio analytics solutions for global and Indian fintech institutions. Proficient in Python, SQL, PyTorch, XGBoost, LSTM, SHAP, and cloud-native Big Data technologies including AWS, Apache Spark, Kafka, and MLflow, with hands-on expertise integrating Bloomberg B-PIPE, Refinitiv, CIBIL, UPI, and NPCI APIs for regulatory-compliant, real-time financial analytics. Demonstrated success in reducing risk, improving approval rates, and delivering scalable, explainable AI solutions across high-volume enterprise systems.

Education

Master of Science, Information Technology and Project Management

Arizona State University, USA

01/08/202301/05/2025

Bachelor of Engineering, Computer Science

Visvesvaraya Technological University, India

01/08/201801/05/2022

Skills

Python

✦

Pandas

✦

NumPy

✦

Scikit-learn

✦

PyTorch

✦

StatsModels

✦

SQL

✦

PostgreSQL

✦

Snowflake SQL

✦

MySQL

✦

R

✦

Supervised

✦

Logistic Regression

✦

Random Forest

✦

Gradient Boosting

✦

XGBoost

✦

LightGBM

✦

LSTM

✦

Temporal CNN

✦

Unsupervised

✦

Isolation Forest

✦

Autoencoders

✦

Anomaly Detection

✦

Explainable AI

✦

SHAP

✦

LIME

✦

Bloomberg B-PIPE

✦

Refinitiv Eikon APIs

✦

ICE Data Services

✦

FIS & SimCorp integrations

✦

CIBIL

✦

Experian

✦

Equifax APIs

✦

UPI transaction analytics

✦

NPCI frameworks

✦

Account Aggregator (AA) API

✦

Payment Gateway APIs

✦

AWS

✦

S3

✦

EC2

✦

Lambda

✦

Glue

✦

EKS

✦

SageMaker

✦

Apache Spark

✦

PySpark

✦

Apache Kafka

✦

Azure

✦

Spark Streaming

✦

MLflow

✦

Kubeflow

✦

Docker

✦

Kubernetes

✦

CI/CD

✦

GitHub Actions

✦

Jenkins

✦

Real-time data pipelines

✦

feature engineering frameworks

✦

integration with financial APIs

✦

enterprise systems

✦

Tableau

✦

Power BI

✦

Plotly Dash

✦

Matplotlib

✦

Seaborn

✦

IAM

✦

Role-based access control

✦

Data encryption

✦

SOC 2

✦

SEC

✦

RBI-compliant logging

✦

Things I have built

SAT Knowledge Matching System

A hybrid retrieval engine that maps student questions to relevant SAT curriculum knowledge points in real time. Built with a custom two-stage pipeline combining TF-IDF keyword retrieval (built from scratch, no sklearn) with a semantic heuristic booster that handles domain alignment, tag overlap, and key concept matching. Covers 30 SAT knowledge points across Math and Reading & Writing. Deployable as a Streamlit web app or CLI tool, with a clean architecture designed to drop in sentence-transformer embeddings as a future upgrade.

Spotify ETL Pipeline on AWS

End-to-end serverless ETL pipeline that extracts playlist and track data from the Spotify API, transforms it into structured datasets, and loads it into Amazon S3 for analytics. Extraction is triggered daily via CloudWatch, with a second Lambda function auto-triggered on S3 upload to transform raw JSON into normalized CSV tables (albums, artists, songs). Schema is inferred automatically via AWS Glue Crawler and exposed for SQL querying through Amazon Athena.

Content-Based Book Recommendation System

Recommendation engine that suggests similar books based on user rating patterns and book metadata. Built a user-item matrix from 250k+ ratings across three datasets, applied cosine similarity to surface the top matches for any given title, and filtered for statistical reliability by requiring a minimum of 250 ratings per book. Outputs are serialized via pickle for deployment in a web interface.

Experience

2025 - Present
Data Scientist
State Street

• Designed predictive liquidity risk models using XGBoost, LSTM time-series networks, and Bloomberg B-PIPE, forecasting portfolio liquidity stress up to 30 days ahead, reducing liquidity risk incidents by 32% across multi-asset portfolios. • Implemented real-time anomaly detection pipelines using Apache Kafka, AWS MSK, Isolation Forests, and Autoencoders, processing 10M+ market events daily, cutting risk detection latency by 45% with sub-200ms response times. • Evaluated and deployed explainable AI frameworks using SHAP, LIME, and Snowflake SQL, providing transparent risk drivers, successfully passing SEC and internal audits with zero model governance findings. • Architected end-to-end MLOps workflows using MLflow, Kubeflow, Docker, Kubernetes on AWS EKS, automating model deployment and monitoring, improving forecasting accuracy by 28% and deployment reliability by 40%. • Developed self-service analytics dashboards using Tableau, Power BI, Plotly Dash, and FIS/SimCorp integrations, enabling portfolio managers to identify stress scenarios 2–4 weeks earlier.

XGBoostLSTMBloomberg B-PIPEApache KafkaAWS MSKIsolation ForestsAutoencodersSHAPLIMESnowflake SQLMLflowKubeflowDockerKubernetesAWS EKSTableauPower BIPlotly DashFISSimCorp
2021 - 2023
Data Scientist
Persistent Systems

• Engineered ML-based credit scoring models using Logistic Regression, Random Forest, Gradient Boosting, and CIBIL/Experian/Equifax APIs, processing 1M+ loan applications per month, reducing loan default rates by 27% and improving approval speed by 60%. • Developed advanced behavioral feature engineering pipelines using Python, Pandas, PySpark, UPI transaction analytics, and Account Aggregator (AA) Framework, increasing approval rates for new-to-credit customers by 22%. • Implemented explainable AI models using SHAP, StatsModels, and Python, ensuring 100% RBI compliance for model transparency and credit risk reporting. • Designed low-latency fraud detection pipelines using Isolation Forest, Autoencoders, Apache Kafka, Spark Streaming, and NPCI/Payment Gateway APIs, detecting 92% of fraudulent transactions in milliseconds while reducing false positives by 35%. • Orchestrated cloud-native ML workflows using AWS S3, EC2, Lambda, Docker, Kubernetes, MLflow, and Jenkins, reducing end-to-end model deployment time by 50% and supporting 20M+ transactions/day.

Logistic RegressionRandom ForestGradient BoostingCIBILExperianEquifax APIsPythonPandasPySparkUPI transaction analyticsAccount Aggregator (AA) FrameworkSHAPStatsModelsIsolation ForestAutoencodersApache KafkaSpark StreamingNPCIPayment Gateway APIsAWS S3EC2LambdaDockerKubernetesMLflowJenkins
Certifications

Let’s make something good.

syed mutaib ali